
Hunyuan3D-2
Updated 11mo ago
[NVIDIA ONLY] Requires 24GB VRAM (Use the lowvram option, it has the same quality). High-Resolution 3D Assets Generation with Large Scale Hunyuan3D Diffusion Models. https://github.com/Tencent/Hunyuan3D-2
[NVIDIA ONLY] Requires 24GB VRAM (Use the lowvram option, it has the same quality). High-Resolution 3D Assets Generation with Large Scale Hunyuan3D Diffusion Models. https://github.com/Tencent/Hunyuan3D-2

Orpheus TTS is an open-source text-to-speech system built on the Llama-3b backbone. Orpheus demonstrates the emergent capabilities of using LLMs for speech synthesis https://github.com/canopyai/Orpheus-TTS
Customizing Realistic Human Photos via Stacked ID Embedding https://huggingface.co/spaces/TencentARC/PhotoMaker-V2

Generate songs with AI (up to 4 min 45 sec). Both with lyrics or instrumental https://github.com/ASLP-lab/DiffRhythm

[NVIDIA Only] Select a portrait, click to move the head around https://github.com/jbilcke-hf/FacePoke

A pinokio script for https://github.com/microsoft/TRELLIS

restore low-res images, restore broken images, recreate a new version of the image with a prompt https://huggingface.co/spaces/fffiloni/InstantIR
An Open Source Model for Audio Samples and Sound Design https://github.com/Stability-AI/stable-audio-tools

Simple Gradio app for generating images with Tongyi-MAI/Z-Image-Turbo.
AuraSR-v2 - An open reproduction of the GigaGAN Upscaler from fal.ai https://huggingface.co/spaces/gokaygokay/AuraSR-v2

Run AI Agent in your browser. https://github.com/browser-use/web-ui

[NVIDIA ONLY] Generate videos with Allegro txt2vid model https://github.com/rhymes-ai/Allegro

Remove objects from an image https://huggingface.co/spaces/OzzyGT/diffusers-image-fill

Phased Consistency Model - generate high quality images with 2 steps https://huggingface.co/spaces/radames/Phased-Consistency-Model-PCM

Dia is a 1.6B parameter text to speech model created by Nari Labs. Dia directly generates highly realistic dialogue from a transcript. You can condition the output on audio, enabling emotion and tone control. The model can also produce nonverbal communications like laughter, coughing, clearing throat, etc. https://github.com/nari-labs/dia
Unify Efficient Fine-Tuning of 100+ LLMs https://github.com/hiyouga/LLaMA-Factory

Multilingual Text-to-Speech with Voice Cloning (Supports: English, Japanese, Korean, Chinese, French, German, Arabic, and Spanish) https://github.com/fishaudio/fish-speech

AutoGPT is a powerful tool that lets you create and run intelligent agents https://github.com/Significant-Gravitas/AutoGPT

Build your own voice for StyleTTS2
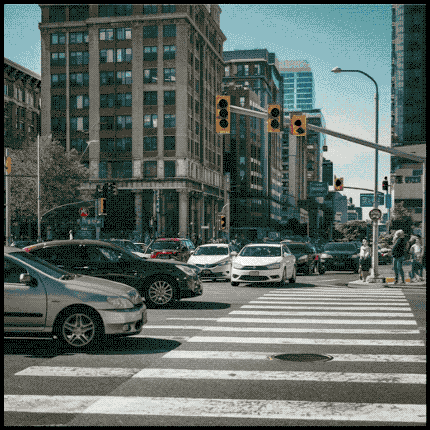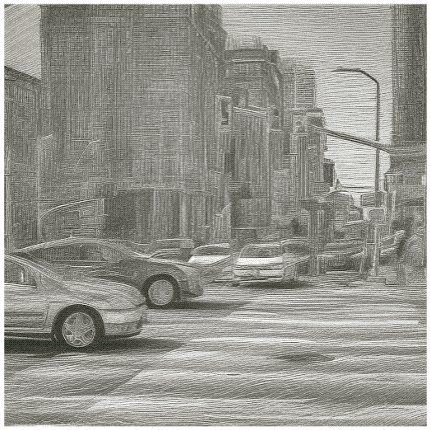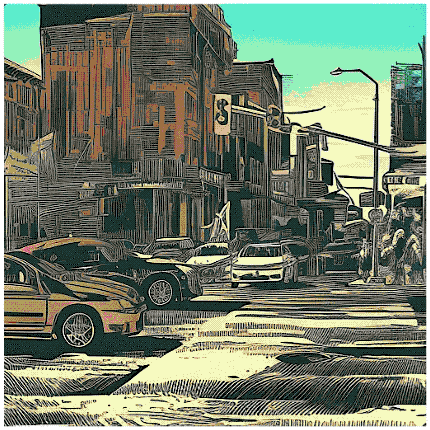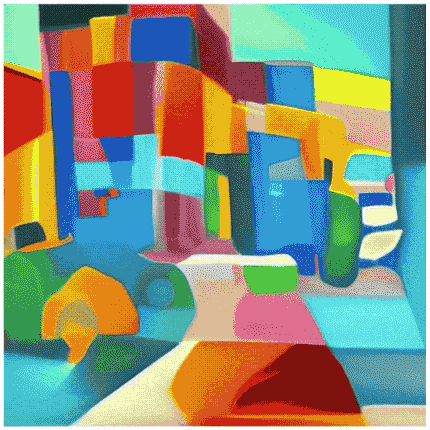
Artist is a training-free text-driven image stylization method. You give an image and input a prompt describing the desired style, Artist give you the stylized image in that style. The detail of the original image and the style you provide is harmonically integrated https://huggingface.co/spaces/fffiloni/Artist