Followed11d ago
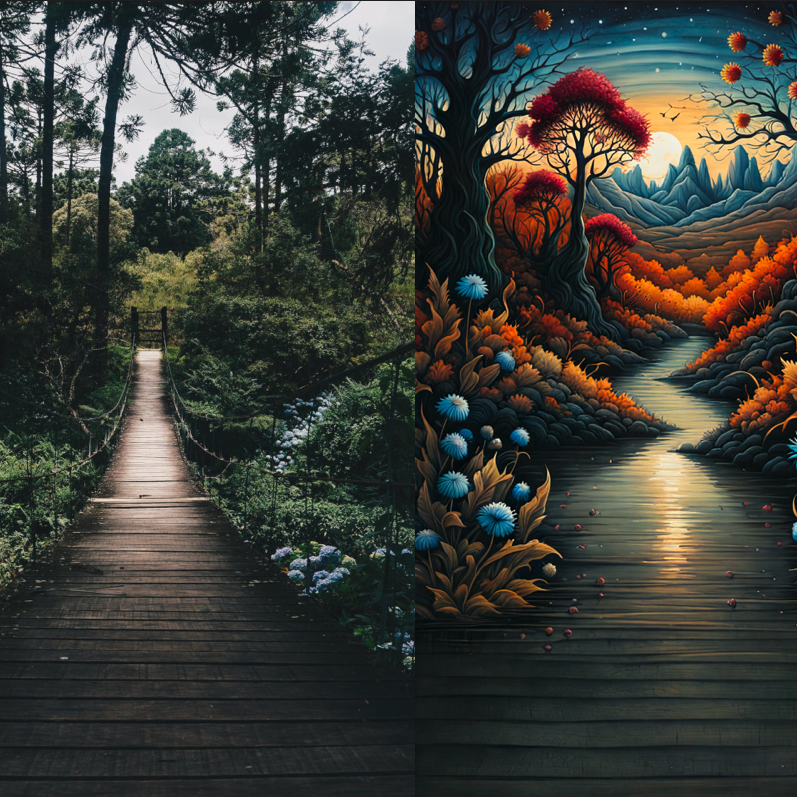
differential-diffusion-uiDifferential Diffusion modifies an image according to a text prompt, and according to a map that specifies the amount of change in each region https://differential-diffusion.github.io/
New projects people are discovering or following across Pinokio.
Differential Diffusion modifies an image according to a text prompt, and according to a map that specifies the amount of change in each region https://differential-diffusion.github.io/
Multi-voice text-to-speech for stories and audiobooks, with local and cloud TTS engines plus optional LLM text processing.
Ming-3.0-tts is an open-source TTS model family with 0.5B dense and 7.9B-A1.3B MoE variants, supporting multilingual speech, voice cloning, voice design, and natural-language control.
job-ops: DevOps principles applied to job hunting. A self-hosted pipeline to track, analyze, and assist your application process
VoxaDub — Local-first AI video and live broadcast dubbing with Hy-MT2 translation and speaker-aware VoxCPM2 voices. Live Dubbing is experimental.
Open-source alternative to Opus Clip, Vidyo.ai, Klap & SubMagic. Turn long-form YouTube videos into viral 9:16 shorts using LLM highlight detection, Whisper transcription, and auto vertical cropping — free, no watermarks, no per-clip credits.

Open-source alternative to Opus Clip, Vidyo.ai, Klap & SubMagic. Turn long-form YouTube videos into viral 9:16 shorts using LLM highlight detection, Whisper transcription, and auto vertical cropping — free, no watermarks, no per-clip credits.

Kokoro, KittenTTS, Higgs audio, Chatterbox/Multi, Fish-Speech, F5 & index-tts & indextts2, VoxCPM and VibeVoice in one app

An all-in-one, 100% local AI video, image & music studio. Its Director mode turns a single prompt into a full music video or short film — LLM-planned, shot by shot. Built on the WanGP pipeline (Wan 2.1/2.2, LTX-2.3, Qwen, Hunyuan Video, Flux). Requires an NVIDIA GPU (6GB+ VRAM).

An all-in-one, 100% local AI video, image & music studio. Its Director mode turns a single prompt into a full music video or short film — LLM-planned, shot by shot. Built on the WanGP pipeline (Wan 2.1/2.2, LTX-2.3, Qwen, Hunyuan Video, Flux). Requires an NVIDIA GPU (6GB+ VRAM).
Real-time Breeze TTS 2 on Apple Silicon (MLX): a local streaming speech server with voice cloning, voice direction and voice design. ~140 ms to first audio on an M4 Pro.

Demonstration for the Qwen-Image-Edit-2511 model with lazy-loaded LoRA adapters for advanced single- and multi-image editing. Supports 7+ specialized LoRAs including photo-to-anime, multi-angle camera control, pose transfer (Any-Pose), upscaling, style transfer, light migration, and manga tone. Features fast inference (4 steps default).

InstantMesh: Efficient 3D Mesh Generation from a Single Image with Sparse-view Large Reconstruction Models

Text Generation model with 9B parameters. Download, explore files and run it on Hugging Face.