A multi-voice AI audiobook generator built on Qwen3-TTS — annotate scripts with an LLM, assign unique voices to each character, per-line style instructions for delivery, clone voices from reference audio, design new voices from text descriptions, train custom voices with LoRA fine-tuning, and export to MP3 or Audacity multi-track projects
[NVIDIA ONLY] Generate Video Progressively. FramePack is a next-frame (next-frame-section) prediction neural network structure that generates videos progressively. https://github.com/lllyasviel/FramePack
A Modular AI Image Generation Web-User-Interface, with an emphasis on making powertools easily accessible, high performance, and extensibility. Supports Stable Diffusion, Flux, etc. AI image models, with plans to support AI video, audio, and more in the future.
cocktailpeanutlabs/differential-diffusion-uiv1.2updated 7mo ago
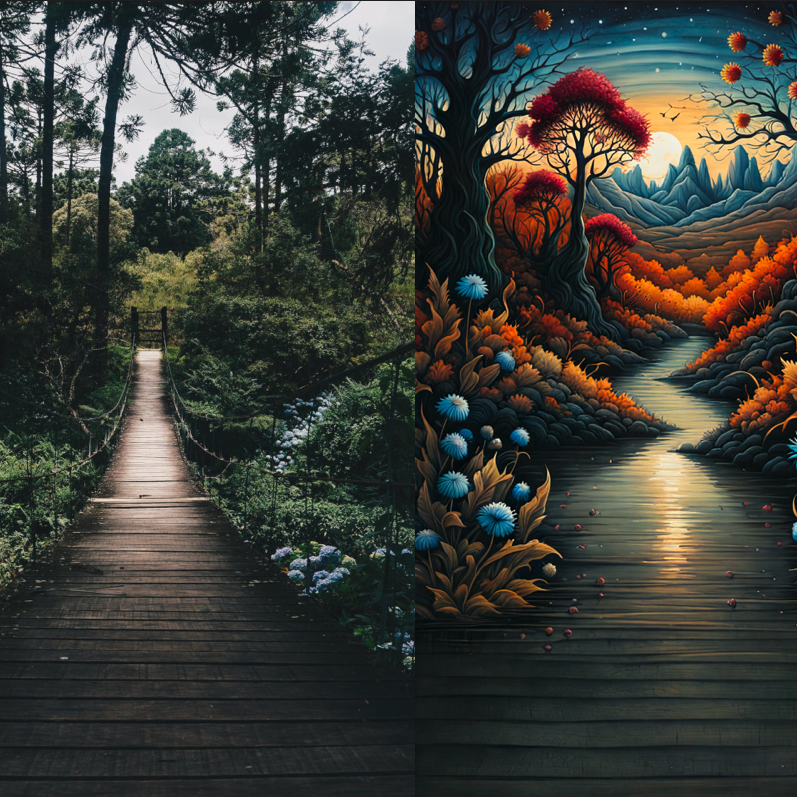
Differential Diffusion modifies an image according to a text prompt, and according to a map that specifies the amount of change in each region https://differential-diffusion.github.io/


 @theawakenone