Pinokio
FeedApps
Download Pinokio
Sign inCreate accountJoin

Apps

Announcements

View all

Updates from app maintainers.

MiniMax H3 Studio
@mvrdvk•3h ago
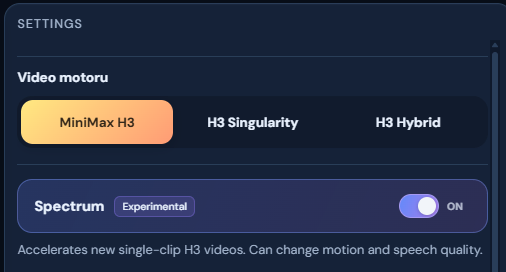
Spectrum acceleration is now available in H3 Studio!Enable it under Settings → Video engine → Spectrum . It’s optional, experimental, and requires no additional LoRA. In our matched 608p test, total render time dropped from 26:15 to 16:06 — 38.65% less time . Recent 1088p clips rendered in around 35 minutes . Compared with my previously observed roughly one-hour renders, that suggests about 42% less time , although this 1088p comparison is approximate. My system: RTX 5060 Ti 16 GB, Ryzen 5 5600X, 32 GB RAM, Windows. Results vary by workload. Spectrum can affect motion and speech, so test a short clip first. H3 Studio now offers three video engines: - MiniMax H3 — the standard engine. - H3 Singularity — an alternative H3 checkpoint. - H3 Hybrid — an experimental H3 checkpoint. Switch between them under Settings → Video engine . Optional engines require their model files to be installed. The Spectrum benchmark above was measured with MiniMax H3 Ref2VA INT8. It does not establish the same speedup for Singularity or Hybrid.
Captionz
@supersoniquestudio•6h ago
1-click Pinokio launcher for Captionz — batch image captioning with local Ollama vision models. What it does Installs and launches Captionz in one click: Install — clones mikecastrodemaria/Captionz into app/, creates a venv and installs the requirements (Pillow, NiceGUI, Gradio). No PyTorch: the models run in Ollama, or in a bundled llama.cpp server (see below). Start (web UI) — runs the NiceGUI interface (python app.py --ui web) and opens it. Start (Gradio UI) — runs the Gradio interface (python gradio_app.py), the same one used on Hugging Face Spaces, here with the Ollama backend. Update — resets the launcher and the app to their origin/main, refreshes deps. Reset — removes app/ (and its venv) to reinstall from scratch. Features (Captionz) Vision-model detection · composed prompts (caption type × length × 20 checkable options × character name) or custom prompt with a live preview · sources: local path, upload, clipboard paste · image preview · editable captions · skip / overwrite / append policy · prefix / suffix (trigger word) · live status (model loading, timer, percent, ETA) · max-tokens cap and thinking switch · dark mode · CLI and benchmark script. See the app repo for full docs. Requirements Pinokio installed. Either Ollama running on the machine (or reachable on the network: change the URL in the UI) with at least one vision model, for example ollama pull qwen3-vl:8b, or no Ollama at all: pick the backend "llama.cpp (sans Ollama)" in the UI. On first captioning Captionz downloads a prebuilt llama-server for your machine (CUDA / Vulkan / CPU / Metal, 150–500 MB) and the default model Qwen2.5-VL-3B-Instruct Q4_K_M (~2.9 GB) into app/llamacpp/. Other GGUF models can be downloaded from Hugging Face or imported from a local Ollama store from the "Modèles llama.cpp…" dialog. Captions are written next to each image as image.txt. How to use Install, then Start (web UI) and click Open Web UI. Pick the vision model, add a folder path (or upload / paste images). Choose a caption type, length and options; check the final prompt preview. Click Captionner tout. Edit any caption in the right panel and save. API Captionz has no HTTP API of its own. Two programmatic entry points exist in app/: Command line (Python, inside the launcher venv) python cli.py ./dataset --recursive --type "Booru tag list" --length short python cli.py ./dataset --model qwen3-vl:8b --option 3 --option 15 --prefix "mystyle, " python cli.py --list-models python cli.py --list-options Python (import the core) import sys; sys.path.insert(0, "app") from pathlib import Path from captionz_core import Settings, Job, make_backend, caption_job s = Settings.load() s.model = "qwen3-vl:8b" s.caption_type, s.caption_length = "Training caption (paragraph)", "long" job = caption_job(Job(Path("photo.jpg")), s, make_backend(s)) print(job.status, job.caption) Gradio UI API (when "Start (Gradio UI)" is running) Gradio exposes every event as an endpoint; open <url>/?view=api for the generated docs, or from Python: from gradio_client import Client, handle_file c = Client("http://127.0.0.1:7860") print(c.view_api()) JavaScript (Gradio client) import { Client } from "@gradio/client"; const c = await Client.connect("http://127.0.0.1:7860"); console.log(await c.view_api()); Curl (Ollama directly, same request Captionz sends) curl http://localhost:11434/api/chat -d '{ "model": "qwen3-vl:8b", "stream": false, "messages": [{"role": "user", "content": "Describe this image in one short sentence.", "images": ["<base64 image>"]}] }'
PhospheneFeatured
@bizarro•1d ago
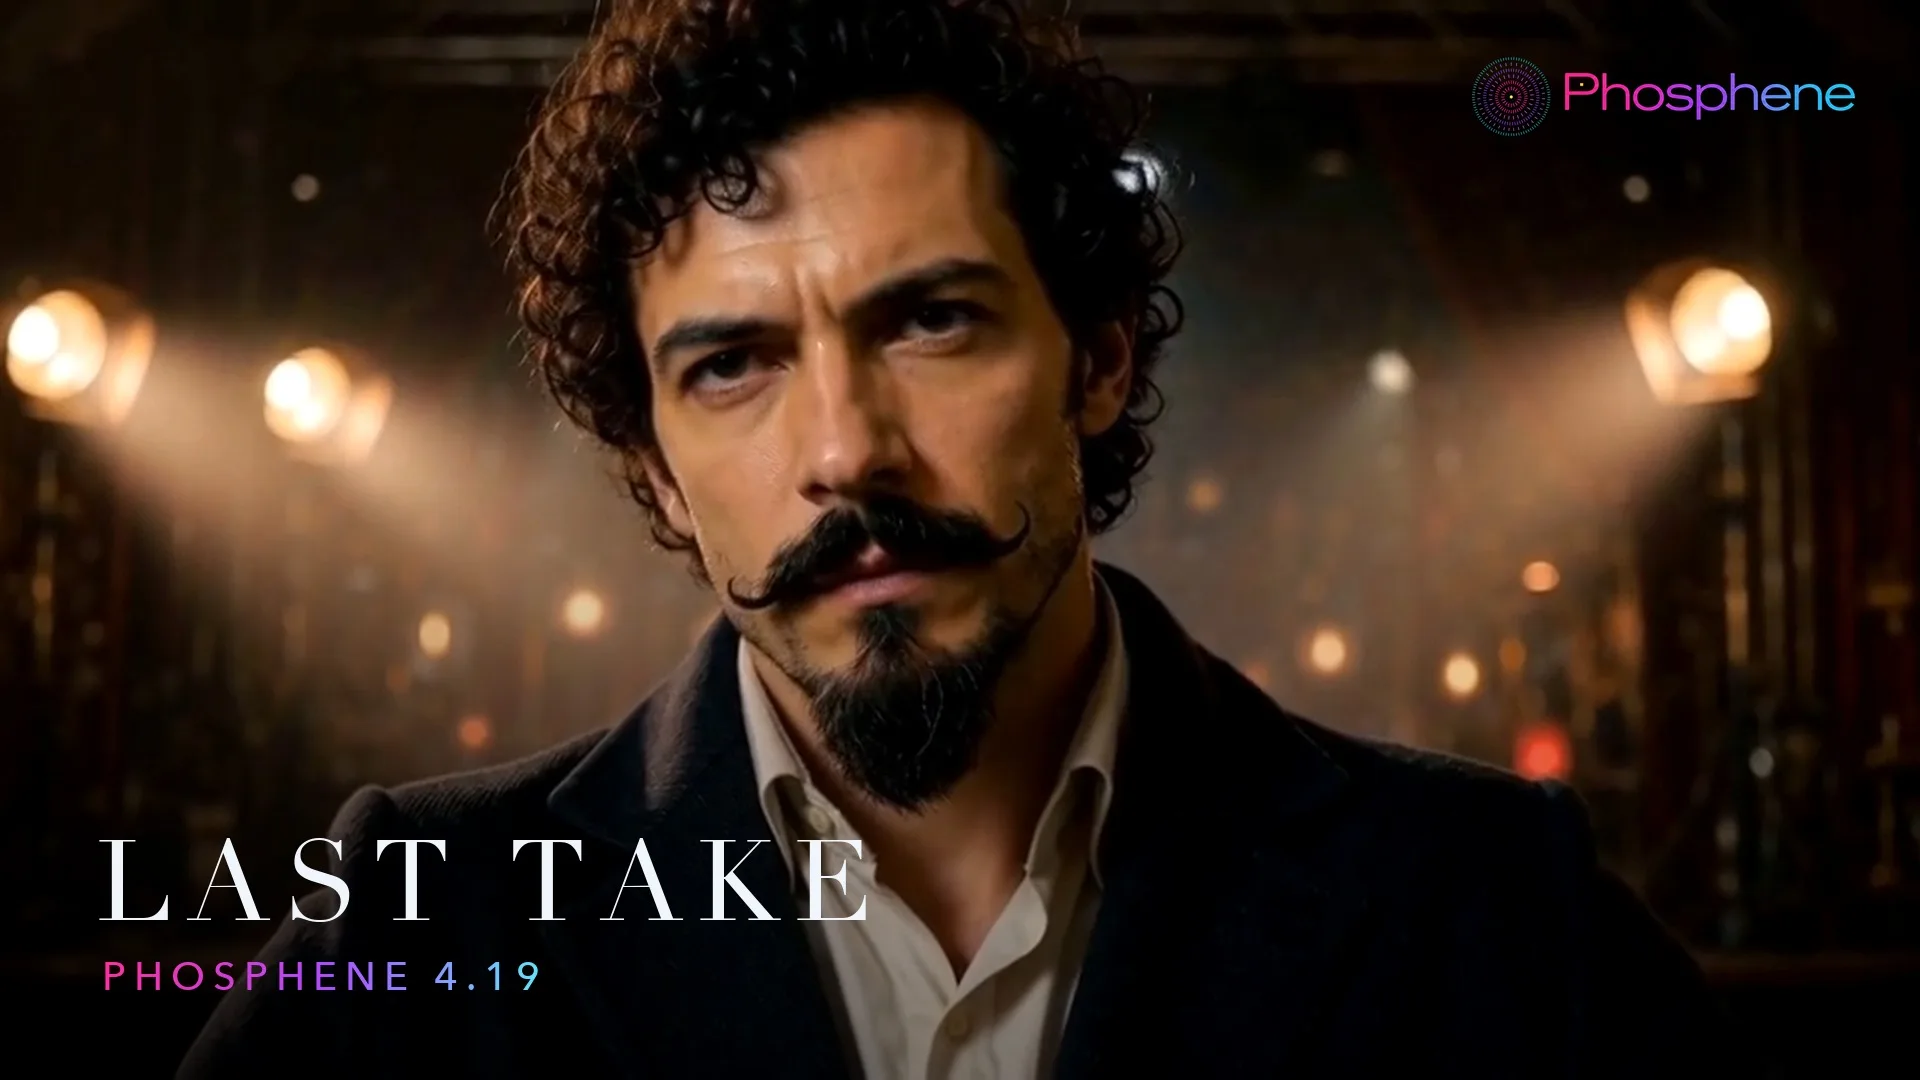
Phosphene 4.19 - Last TakeOne night, one director, one take before the sun comes up. Every shot, every sound and the song were made in Phosphene on one Mac. - The rain on the backlot was a silent clip. Add sound wrote the rain and the thunder that hits right on the lightning, and kept every frame exactly as it was. - The stage coming alive is Keyframes: one dark frame with only the ghost light on, one fully lit frame, and Hailuo H3 made everything in between. Extend then carried it 5 more seconds. - The long push-in on Bizarro is a 5 second clip made longer twice with Extend. Each new piece carries the last frames and their sound, so it plays as one unbroken 15 second move. - The film camera rolling is Fast HD: a quick small H3 render, finished at 1280x768 by LTX's x2 Upscale & Face Fix. - The finale is Lip-sync on H3 with our own song: the song is kept exactly, only his face is made to sing it. The song itself came out of Phosphene's Music Studio and scores the whole film. Also in 4.19: - 10 and 15 second H3 shots join more smoothly (the jump in sound at the seam is mostly gone). - Fast HD: about a third quicker than High, for previews and quick drafts. - Extending a clip again and again no longer wears it down ( 48) - Characters you trained in Phosphene finally look like who you trained - thank you @tanis2000 ( 62) 4.19.1: voices trained on 4.19.0 are repaired on Update, a failed training now says why, and the Stop early button no longer covers the time left (thanks @blackest) Press Update in Pinokio, then restart. https://github.com/mrbizarro/Phosphene/releases/tag/v4.19.0
Iris-3B Studio
@thomas_eric•2d ago
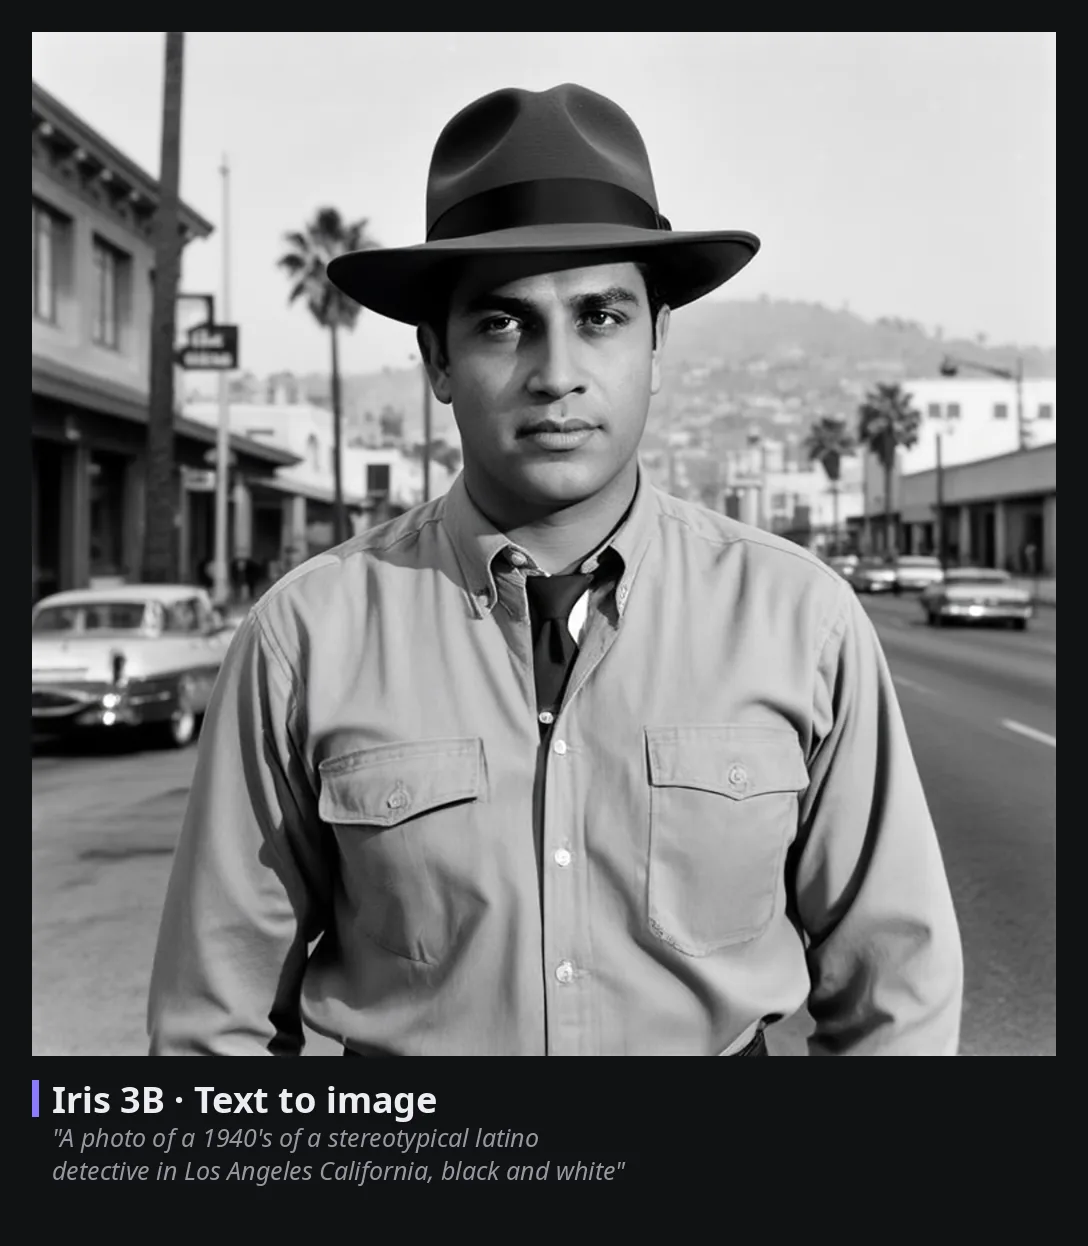
Iris 3B Studio is Now Available!Iris 3B Studio is Now Available! Not only is a incredible text-to-image model, but it also has upscaling capabilities and depth map generation!
SeedVR2-7B MLX
@rdx_ai•3d ago
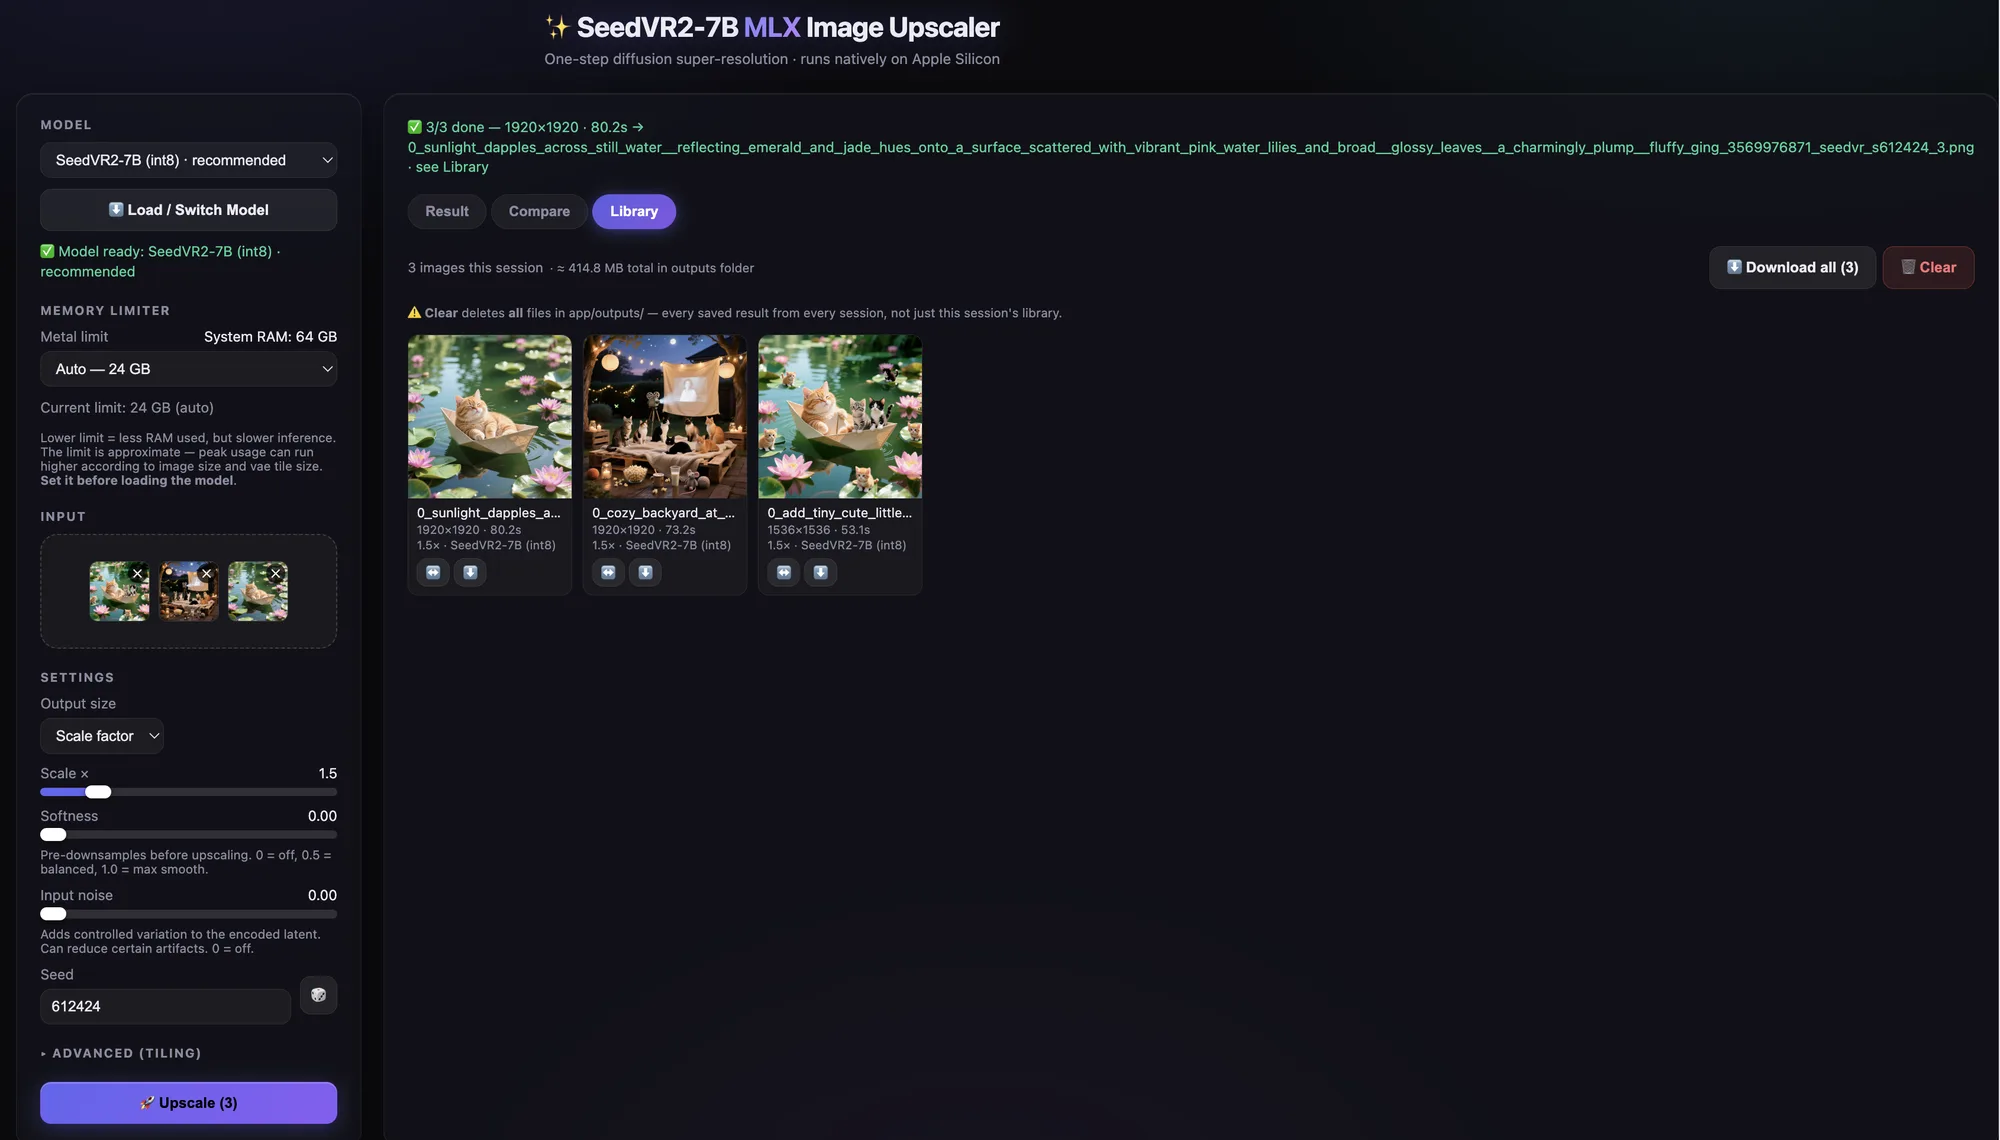
New Update with Multiple/batch import, Library tab!Updated with Multiple/batch import support, New Library tab for viewing multiple images in a session.. Fastest and most Memory Efficient Seedvr2 implementation for Apple Silicon Mac..
LightOnOCR 3
@cocktailpeanut•3d ago
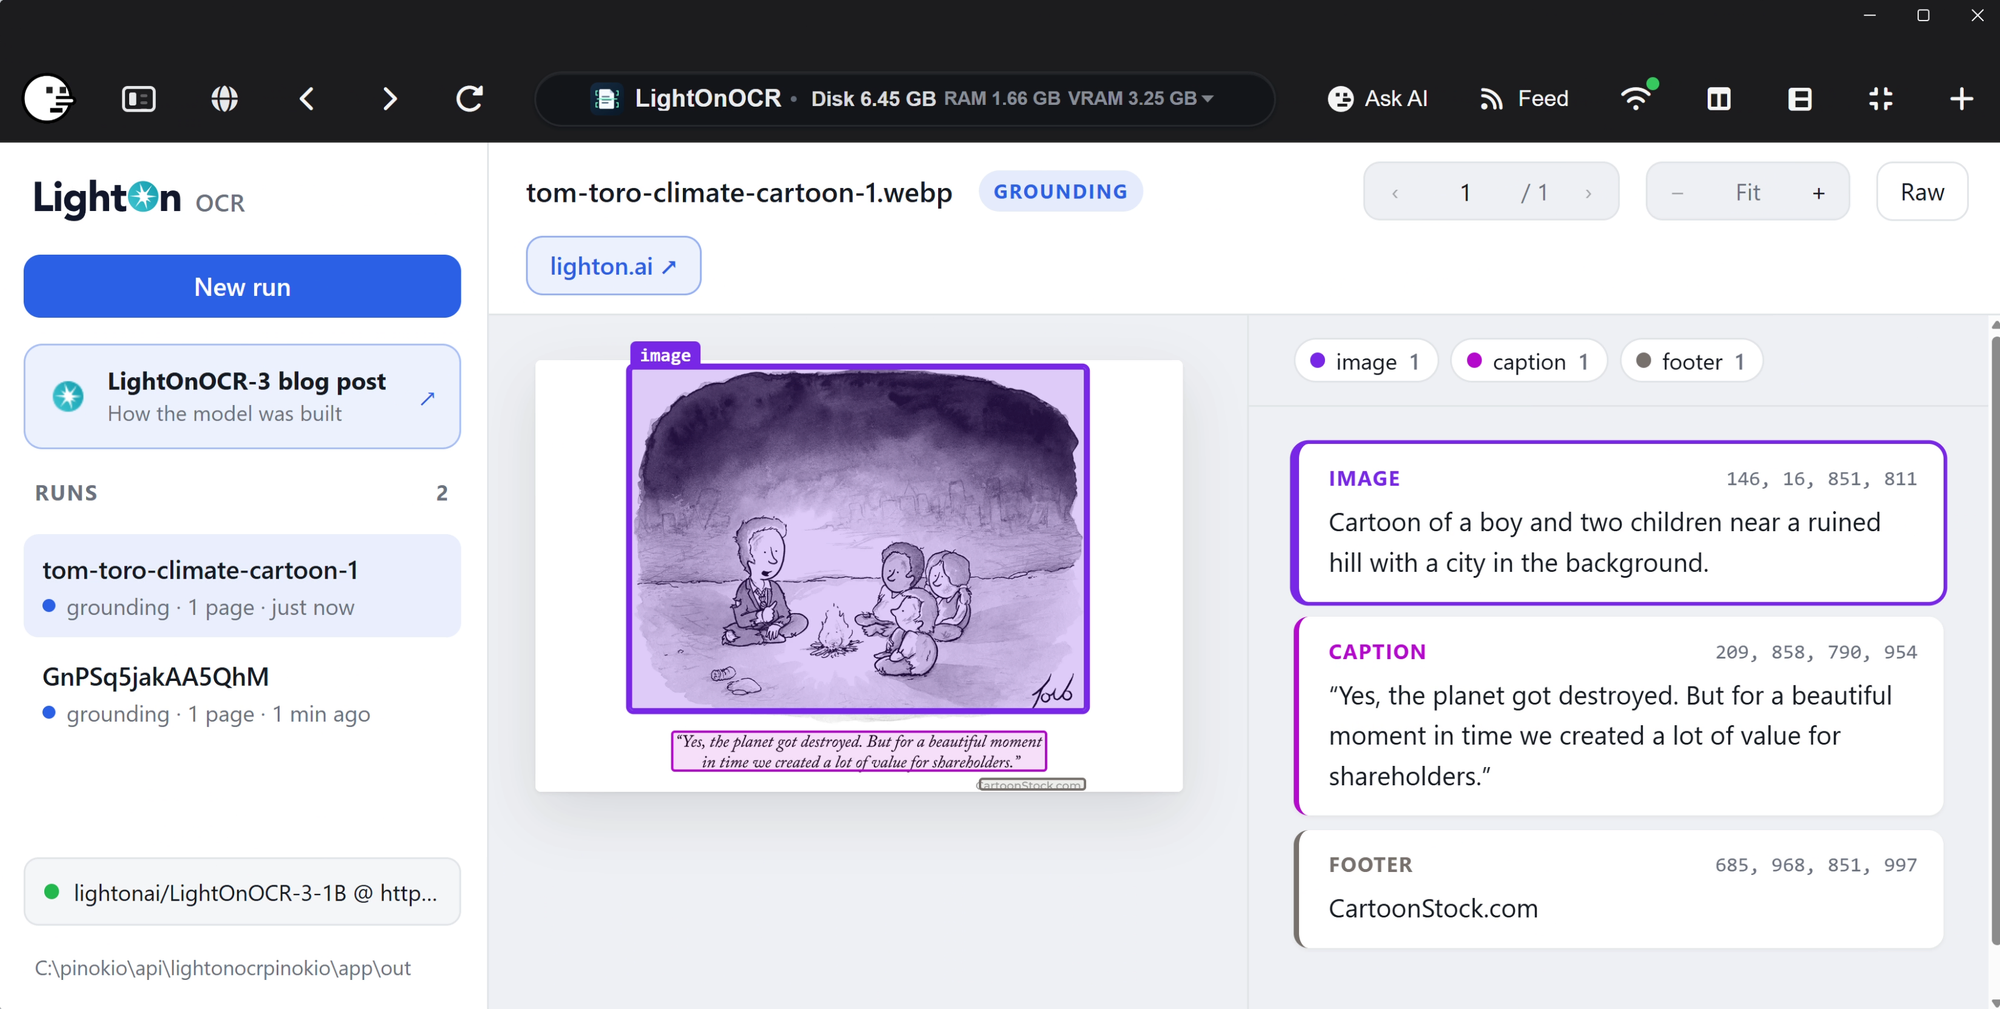
LightOnOCR-3: Turn PDFs and images into structured text locally (Mac, Windows, Linux)LightOnOCR 3 is now available on Pinokio. It's a sequel to the LightOnOcr 2 model, which you can try here (thanks to @theawakenone ) https://pinokio.co/apps/github-com-theawaken1-lightonocr-2-1b-pinokio This LightOnOCR 3 launcher implements the backend using huggingface transformers and lets you run 3 variations of the model: - 0.8B - 1B - 4B The launcher includes LightOn’s original web interface, available at: https://github.com/lightonai/LightOnOCR Demo Here's how it works. You just launch the app and open any PDF or image file: Features - View the source document alongside the extracted text - inspect layout boxes showing where content came from - revisit previous runs. Examples
Type:api
apipluginAll
Platform:All
AllmacOSWindowsLinux
GPU:All
AllNVIDIAAMDApple
Sort by
RecommendedLatestCheck-ins
#ai191#tts60#image-generation46#video-generation40#137#utility35#music33#próba27
PulseForgeFeatured
A fully local, cross-platform audio visualizer editor. Create reactive music videos with layered graphics, AI-transcribed lyrics, and frame-perfect MP4 exports — all running in your browser
TheAwaken1/PulseForgev5.0updated 5d ago
#music#audio-visualization
@theawakenone3 check-insNVIDIAAMDApple
theDAWFeatured
Full-featured DAW, DJ, and VJ app interoperable w/Ableton, Reaper, Resolume & more. Stable Audio 3, Magenta RT2, Lyria 3 Pro, Suno API, Chimera track fusion, Demucs stems, MIDI generate/notate, rule-based composer (harmony, counterpoint, fugue), orchestra sound bank w/concert-hall reverb, VST3 instruments, MPE, native Audima Labs Sway support, img > spectrogram > music, drawing > music, VST3 & .gan plugins, automix & key-lock, GLSL shaders, volumetric video, Quest 3 XR interface, MIDI auto-map, RAG assistant, asset library with example projects
gantasmo/theDAW-Pinokiov7.0updated 6d ago
#music#daw#music-studio
@gantasmo8 check-insNVIDIAAMDApple
God's Eye ViewFeatured
A live 3D intelligence console for planet Earth.
bilawalsidhu/gods-eye-viewv3.6updated 1 min ago
#god's-eye-view#godseye#osint
@bilawalsidhu366 check-insNVIDIAAMDApple
MiniJamFeatured
Describe any song in plain English, compose a structured caption and lyrics locally, and generate it with MiniMax Music 3.
cocktailpeanut/minijamv7.0updated 1mo ago
#music-generation#ai#musicgen
@cocktailpeanut1 check-inNVIDIAAMDApple
MiniMax H3 ComfyUIFeatured
MiniMax H3 omni-modal video generation in ComfyUI. Text/image/video/audio in, video with native 32kHz stereo audio out (768p default, 1080p+ supported). Disk-optimized: pruned INT8 + NVFP4 weights (~63GB instead of ~290GB). NVIDIA only.
ThomasEricB/minimax-h3-pinokiov8.0updated 1d ago
#minimax#video-generation#comfyui
@thomas_eric50 check-insNVIDIAAMDApple
SongGeneration StudioFeatured
AI Song Generation with Full Style Control - Generate complete songs with lyrics, vocals, and instrumental tracks using Tencent AI Lab's SongGeneration (LeVo) model. [NVIDIA ONLY]
6Morpheus6/SongGeneration-Studiov3.7updated 10d ago
#music#song#audio
@morpheus20 check-insNVIDIAAMDApple
ai-toolkitFeatured
AI Toolkit by Ostris
pinokiofactory/ai-toolkitv3.7updated 5d ago
#ai#trainer#training
6 check-insNVIDIAAMDApple
AgentsViewFeatured
Browse, search, and analyze sessions from Claude Code, Codex, and other coding agents locally.
cocktailpeanut/agentsview.pinokiov8.0updated 2mo ago
#claude#agent#agents
@cocktailpeanut5 check-insNVIDIAAMDApple
GeoLibreFeatured
A free, open-source GIS for visualizing, exploring, and analyzing geospatial data locally in your browser.
cocktailpeanut/geolibre.pinokiov7.0updated 3mo ago
#gis
@cocktailpeanut4 check-insNVIDIAAMDApple
Uncensored Local StudioFeatured
Run image generation, GGUF language models, Whisper speech recognition, and Kokoro speech synthesis locally from one offline studio.
cocktailpeanut/uncensored-local-studio.pinokiov8.0updated 3d ago
#image-generation#llm#ai
@cocktailpeanut31 check-insNVIDIAAMDApple
MuScriptorFeatured
Local multi-instrument audio-to-MIDI transcription from Kyutai and Mirelo.
cocktailpeanut/muscriptor.pinokiov8.0.0updated 5d ago
#music#audio#midi
@cocktailpeanut24 check-insNVIDIAAMDApple
MaestroFeatured
An all-in-one, 100% local AI creative studio, director, and multi-track editor. Generate with MiniMax H3, LTX-2.5/2.3, Wan, Flux, Qwen, and more; turn an idea or song into a planned production; then finish it on the timeline. Requires an NVIDIA GPU (6GB+ VRAM).
Blizaine/Maestrov8.0updated 4h ago
#maestro#video-generation#music
@blizaine254 check-insNVIDIAAMDApple
UnderfitFeatured
LoRA fine-tuning dashboard for Stable Audio 3
cocktailpeanut/underfit.pinokiov7.0updated 2mo ago
#lora#music#ai
@cocktailpeanut6 check-insNVIDIAAMDApple
StableDAWFeatured
Browser-based AI audio DAW for Stable Audio 3 with text-to-audio, inpainting, LoRA training, FFmpeg effects, waveform editing, sequencer, piano roll, and persistent library. https://github.com/gantasmo/stabledaw
cocktailpeanut/stabledaw.pinokiov7.0updated 1mo ago
#audio#daw#music
@cocktailpeanut26 check-insNVIDIAAMDApple
Image to PromptFeatured
Generate editable Ideogram JSON prompts from uploaded images.
cocktailpeanut/image-to-promptv7.0updated 15d ago
#ideogram#ai#prompt-helper
@cocktailpeanut10 check-insNVIDIAAMDApple
IdeopromptFeatured
Describe an image, get a 100% schema-valid Ideogram 4 JSON prompt — generated fully locally with an embedded llama.cpp (no Ollama or LM Studio required).
cocktailpeanut/ideopromptv7.0updated 2mo ago
#prompt-helper#ai#prompting
@cocktailpeanut1 check-inNVIDIAAMDApple
Wan2GP - AMDFeatured
[AMD ONLY] Super Optimized Gradio UI for AI video creation for GPU poor machines (6GB+ VRAM). Supports Wan 2.1/2.2, Qwen, Hunyuan Video, LTX Video, Flux and more. (On Windows supported by all dedicated AMD GPUs from RDNA 2 - RDNA 4)
6Morpheus6/wan2gp-amdv8.0updated 2d ago
#video-generation#wan2gp#video
@morpheus191 check-insNVIDIAAMDApple
OdysseusFeatured
Self-hosted AI workspace for local-first chat, agents, tools, memory, research, documents, email, and model endpoint management.
cocktailpeanut/odysseus.pinokiov7.0updated 17d ago
#odysseus#agent#ai
@cocktailpeanut13 check-insNVIDIAAMDApple
SearXNGFeatured
A privacy-respecting metasearch engine that runs locally.
cocktailpeanut/searxng.pinokiov7.0updated 3mo ago
#search#searchengine
@cocktailpeanut7 check-insNVIDIAAMDApple
TripoSplatFeatured
Image-to-3D Gaussian splat generation from VAST-AI-Research. Requires a CUDA-capable GPU.
cocktailpeanut/triposplat.pinokiov7.0updated 2mo ago
#3d#gaussian#3dgen
@cocktailpeanut5 check-insNVIDIAAMDApple
Previous
12345...9
NextPage 1 of 9

Global feed

Latest posts from the community.

can it create animated prompts of an uploaded image?
@arif1979 · Image to Prompt
not working at all...
@akos2 · SeedVR2-7B MLX
I think a 4-step turbo version is out? https://github.com/speridlabs/iris-3b iris-3b-turbo
@cocktailpeanut · Iris-3B Studio
Checked in to Wan2GP.
@lucassribeiro · Community
Maestro: [Runtime] FlashAttention is unavailable (No module named 'flash_attn'); continuing with SageAtt…
@ilovergb · Maestro
App: Maestro (Maestro.git) Repo: https://github.com/Blizaine/Maestro.git Generated: 2026-10-12T19:20:...
More

Global radar

Projects getting attention.

Discovered·just now
free-video-generator
Completely free AI video generator — no GPU, no subscription, no limits. Built on Agnes AI free models.
Followed·2 min
Wan2GP
Super Optimized Gradio UI for AI video creation for GPU poor machines (6GB+ VRAM). Supports Wan 2.1/2.2, Qwen, Hunyuan Video, LTX Video and Flux. https://github.com/deepbeepmeep/Wan2GP
Followed·2 min
HeartMuLa Studio
A professional, Suno-like music generation studio for HeartLib. https://github.com/fspecii/HeartMuLa-Studio
Followed·3 min
Maestro
An all-in-one, 100% local AI creative studio, director, and multi-track editor. Generate with MiniMax H3, LTX-2.5/2.3, Wan, Flux, Qwen, and more; turn an idea or song into a planned production; then finish it on the timeline. Requires an NVIDIA GPU (6GB+ VRAM).
Followed·4 min
SongGeneration Studio
AI Song Generation with Full Style Control - Generate complete songs with lyrics, vocals, and instrumental tracks using Tencent AI Lab's SongGeneration (LeVo) model. [NVIDIA ONLY]
More
Pinokio
PrivacyTerms
FeedApps