Pinokio
FeedApps
Download Pinokio
Sign inCreate accountJoin

Apps

Announcements

View all

Updates from app maintainers.

MiniMax H3 Studio
@mvrdvk•6h ago
Continuum Update (v2026‑10‑14)Continuum now supports two ways to build longer videos: - Single Prompt: Repeat one prompt across the selected number of sections. - Per Section: Write a separate prompt for each section. What’s improved - Fixed an issue that could regenerate earlier sections when extending a video. - Added shared character and setting text for every new section. - Added Balanced (22 frames) and experimental Strong (39 frames) transition context. - Continuations preserve the original seed, model settings, shared context and transition preset. - The interface now shows existing duration + added duration \= total duration . Validated with Studio Draft settings: 480p, 12 steps, 5 + 5 seconds. Saved-section reuse was confirmed, and both stickman fighters remained in the scene as the action continued into combat. Spectrum compatibility: Spectrum is bypassed in Continuum because it interfered with safe saved-section reuse. It remains available for ordinary H3 generation. Older Spectrum-enabled Continuum runs require a new series; existing videos are preserved. Continuum remains experimental . Character details, camera, lighting and motion can still drift. Strong context is not always better, so Balanced remains the default. Audio continuity and longer sequences need further testing. Update through Pinokio, restart Studio when the queue is idle, and refresh the page. ☕ Support development: https://buymeacoffee.com/erdindev
Captionz
@supersoniquestudio•2d ago
1-click Pinokio launcher for Captionz — batch image captioning with local Ollama vision models. What it does Installs and launches Captionz in one click: Install — clones mikecastrodemaria/Captionz into app/, creates a venv and installs the requirements (Pillow, NiceGUI, Gradio). No PyTorch: the models run in Ollama, or in a bundled llama.cpp server (see below). Start (web UI) — runs the NiceGUI interface (python app.py --ui web) and opens it. Start (Gradio UI) — runs the Gradio interface (python gradio_app.py), the same one used on Hugging Face Spaces, here with the Ollama backend. Update — resets the launcher and the app to their origin/main, refreshes deps. Reset — removes app/ (and its venv) to reinstall from scratch. Features (Captionz) Vision-model detection · composed prompts (caption type × length × 20 checkable options × character name) or custom prompt with a live preview · sources: local path, upload, clipboard paste · image preview · editable captions · skip / overwrite / append policy · prefix / suffix (trigger word) · live status (model loading, timer, percent, ETA) · max-tokens cap and thinking switch · dark mode · CLI and benchmark script. See the app repo for full docs. Requirements Pinokio installed. Either Ollama running on the machine (or reachable on the network: change the URL in the UI) with at least one vision model, for example ollama pull qwen3-vl:8b, or no Ollama at all: pick the backend "llama.cpp (sans Ollama)" in the UI. On first captioning Captionz downloads a prebuilt llama-server for your machine (CUDA / Vulkan / CPU / Metal, 150–500 MB) and the default model Qwen2.5-VL-3B-Instruct Q4_K_M (~2.9 GB) into app/llamacpp/. Other GGUF models can be downloaded from Hugging Face or imported from a local Ollama store from the "Modèles llama.cpp…" dialog. Captions are written next to each image as image.txt. How to use Install, then Start (web UI) and click Open Web UI. Pick the vision model, add a folder path (or upload / paste images). Choose a caption type, length and options; check the final prompt preview. Click Captionner tout. Edit any caption in the right panel and save. API Captionz has no HTTP API of its own. Two programmatic entry points exist in app/: Command line (Python, inside the launcher venv) python cli.py ./dataset --recursive --type "Booru tag list" --length short python cli.py ./dataset --model qwen3-vl:8b --option 3 --option 15 --prefix "mystyle, " python cli.py --list-models python cli.py --list-options Python (import the core) import sys; sys.path.insert(0, "app") from pathlib import Path from captionz_core import Settings, Job, make_backend, caption_job s = Settings.load() s.model = "qwen3-vl:8b" s.caption_type, s.caption_length = "Training caption (paragraph)", "long" job = caption_job(Job(Path("photo.jpg")), s, make_backend(s)) print(job.status, job.caption) Gradio UI API (when "Start (Gradio UI)" is running) Gradio exposes every event as an endpoint; open <url>/?view=api for the generated docs, or from Python: from gradio_client import Client, handle_file c = Client("http://127.0.0.1:7860") print(c.view_api()) JavaScript (Gradio client) import { Client } from "@gradio/client"; const c = await Client.connect("http://127.0.0.1:7860"); console.log(await c.view_api()); Curl (Ollama directly, same request Captionz sends) curl http://localhost:11434/api/chat -d '{ "model": "qwen3-vl:8b", "stream": false, "messages": [{"role": "user", "content": "Describe this image in one short sentence.", "images": ["<base64 image>"]}] }'
PhospheneFeatured
@bizarro•3d ago
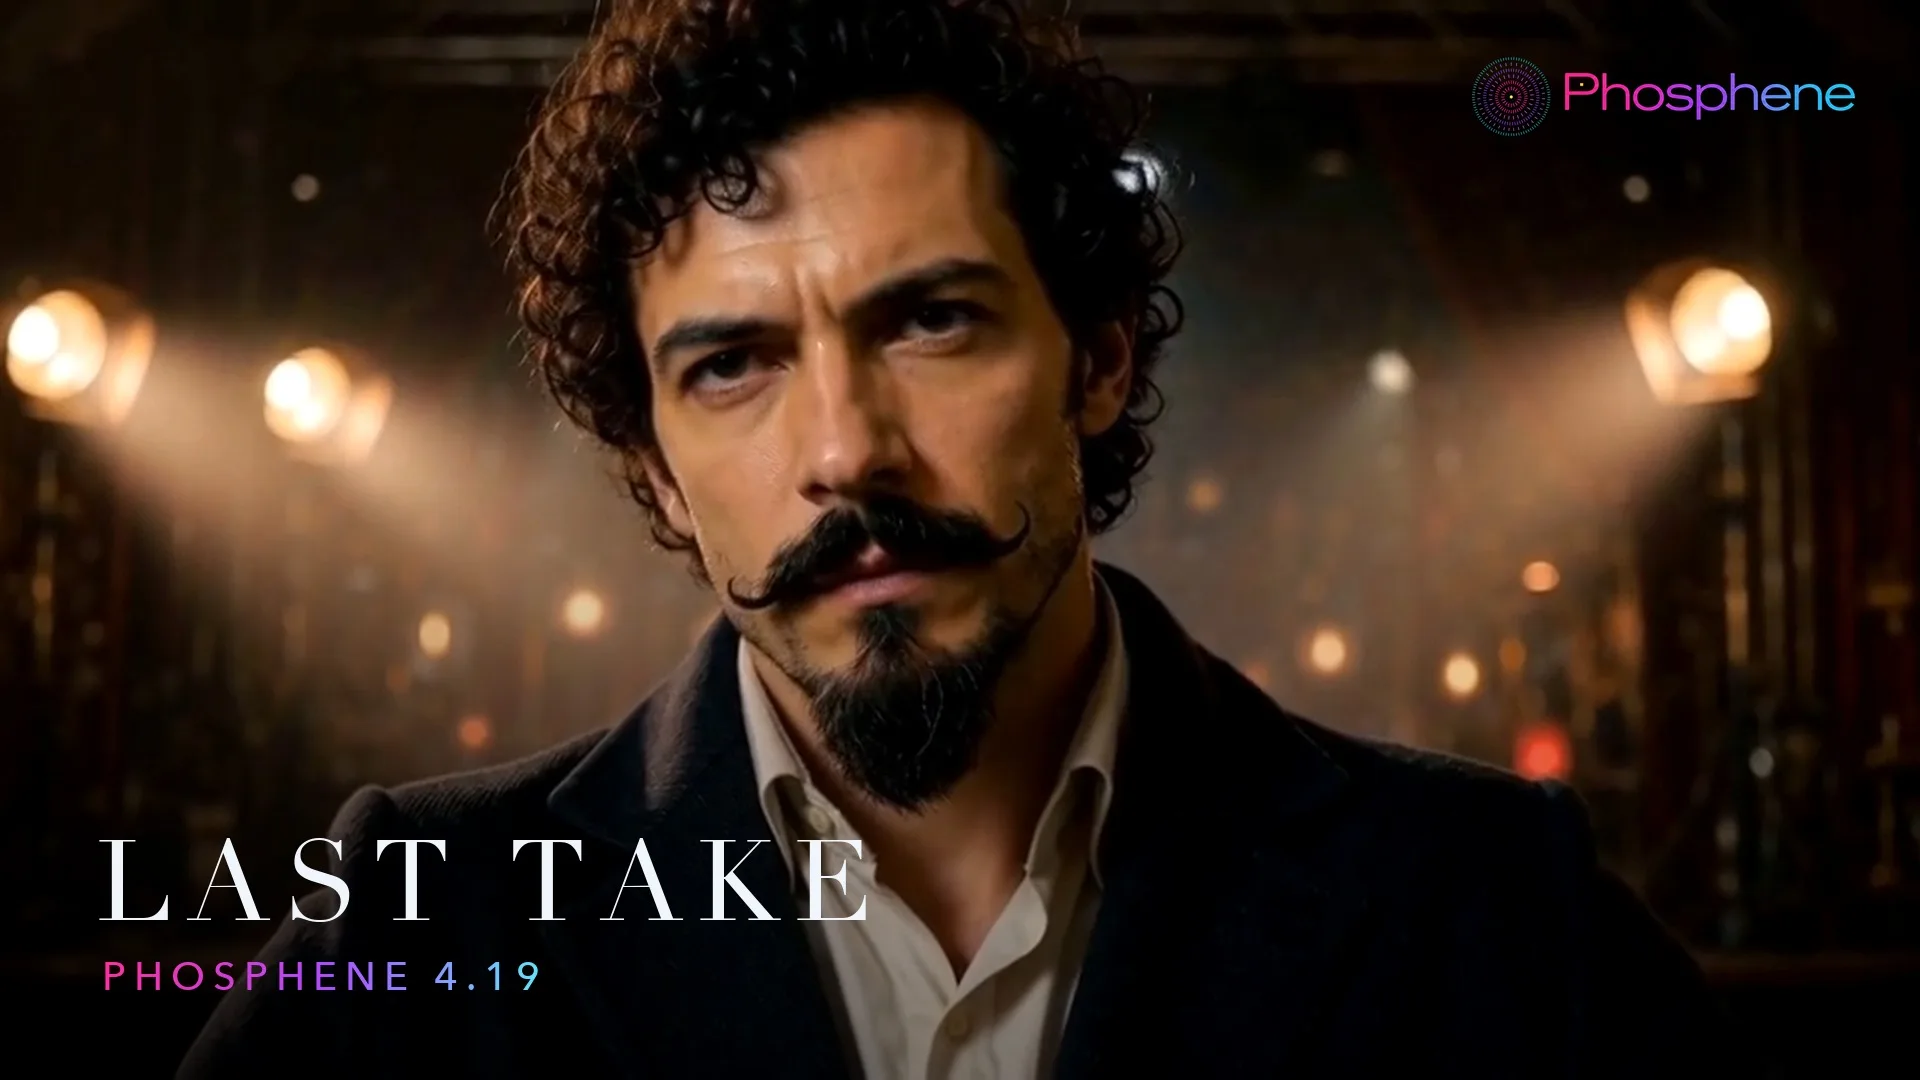
Phosphene 4.19 - Last TakeOne night, one director, one take before the sun comes up. Every shot, every sound and the song were made in Phosphene on one Mac. - The rain on the backlot was a silent clip. Add sound wrote the rain and the thunder that hits right on the lightning, and kept every frame exactly as it was. - The stage coming alive is Keyframes: one dark frame with only the ghost light on, one fully lit frame, and Hailuo H3 made everything in between. Extend then carried it 5 more seconds. - The long push-in on Bizarro is a 5 second clip made longer twice with Extend. Each new piece carries the last frames and their sound, so it plays as one unbroken 15 second move. - The film camera rolling is Fast HD: a quick small H3 render, finished at 1280x768 by LTX's x2 Upscale & Face Fix. - The finale is Lip-sync on H3 with our own song: the song is kept exactly, only his face is made to sing it. The song itself came out of Phosphene's Music Studio and scores the whole film. Also in 4.19: - 10 and 15 second H3 shots join more smoothly (the jump in sound at the seam is mostly gone). - Fast HD: about a third quicker than High, for previews and quick drafts. - Extending a clip again and again no longer wears it down ( 48) - Characters you trained in Phosphene finally look like who you trained - thank you @tanis2000 ( 62) 4.19.1: voices trained on 4.19.0 are repaired on Update, a failed training now says why, and the Stop early button no longer covers the time left (thanks @blackest) Press Update in Pinokio, then restart. https://github.com/mrbizarro/Phosphene/releases/tag/v4.19.0
Iris-3B Studio
@thomas_eric•4d ago
Iris 3B Studio is Now Available!Iris 3B Studio is Now Available! Not only is a incredible text-to-image model, but it also has upscaling capabilities and depth map generation!
SeedVR2-7B MLX
@rdx_ai•5d ago
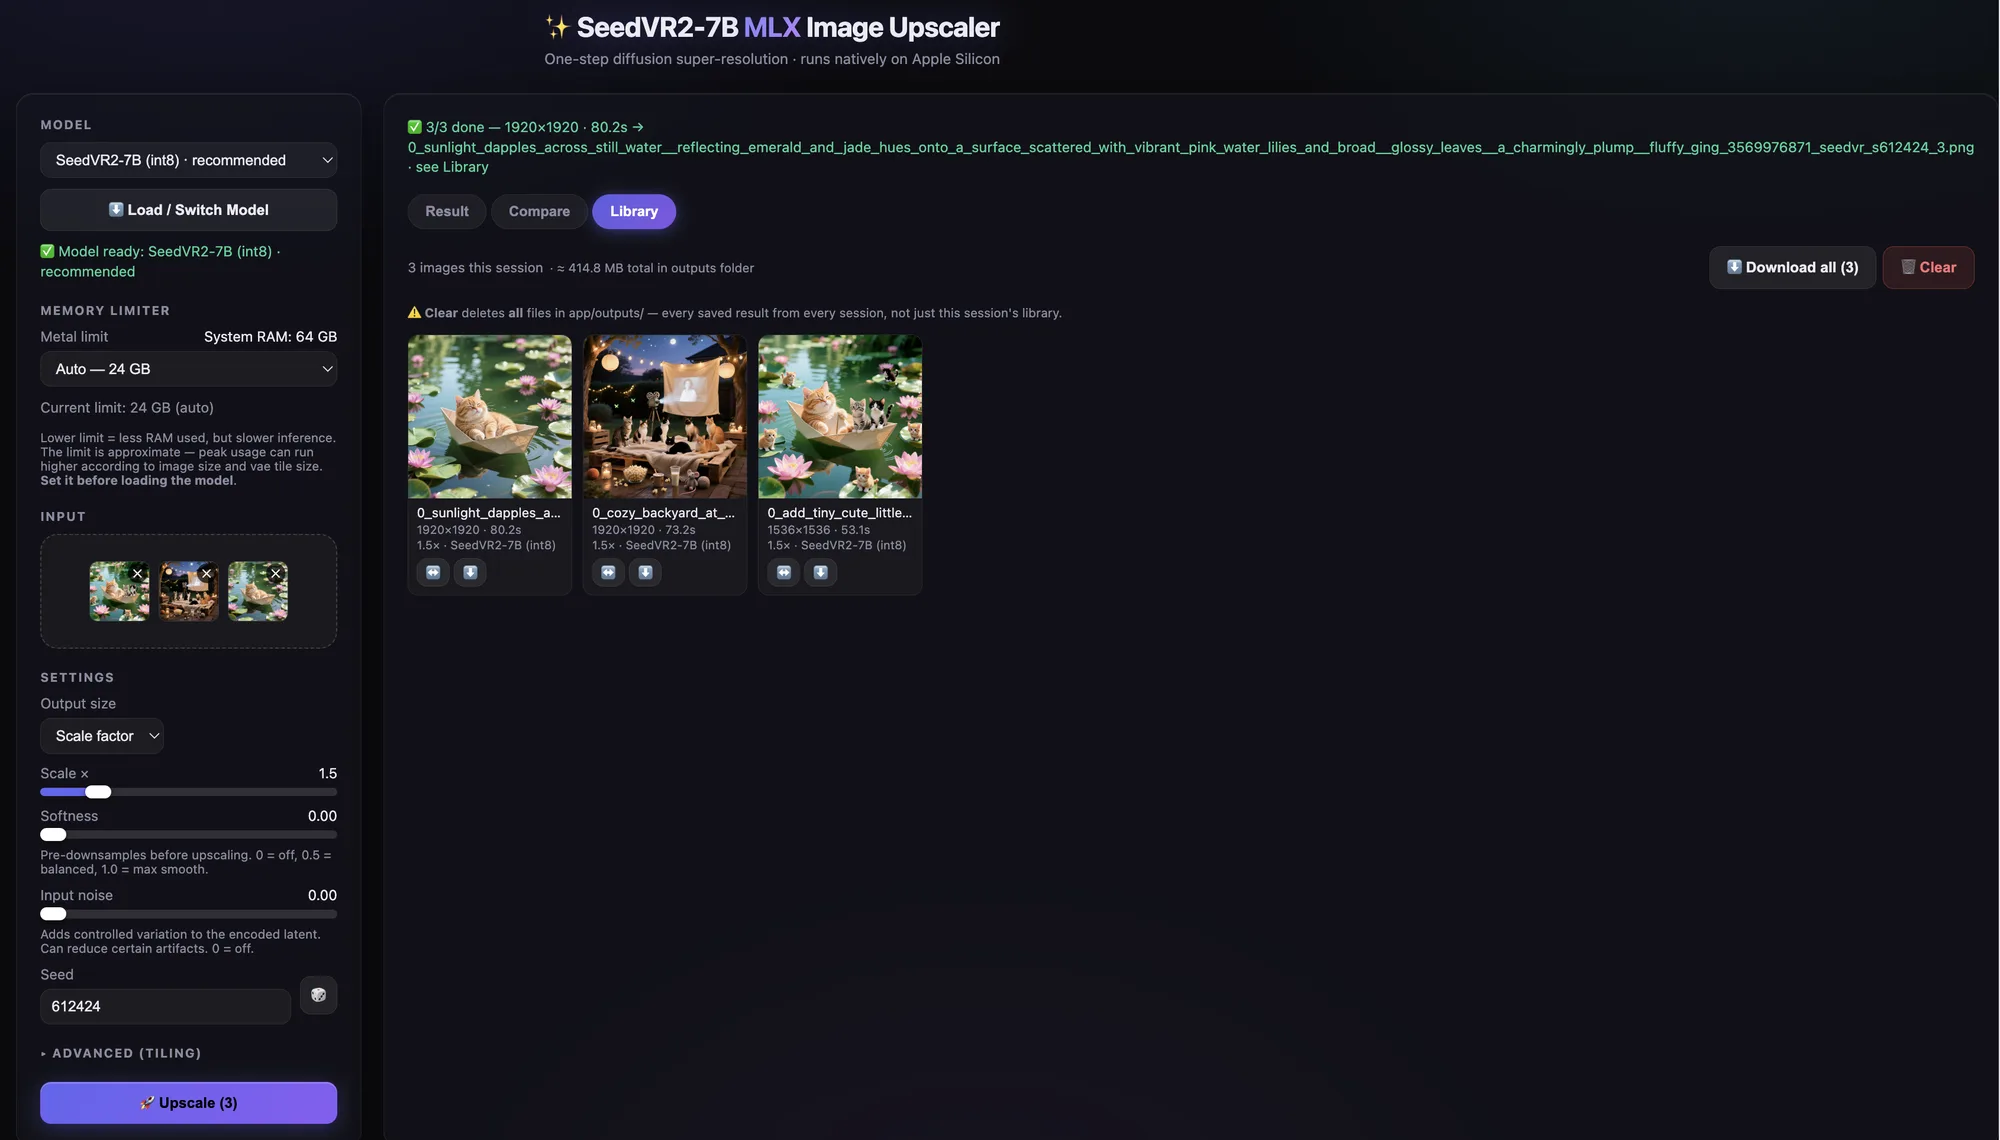
New Update with Multiple/batch import, Library tab!Updated with Multiple/batch import support, New Library tab for viewing multiple images in a session.. Fastest and most Memory Efficient Seedvr2 implementation for Apple Silicon Mac..
LightOnOCR 3
@cocktailpeanut•5d ago
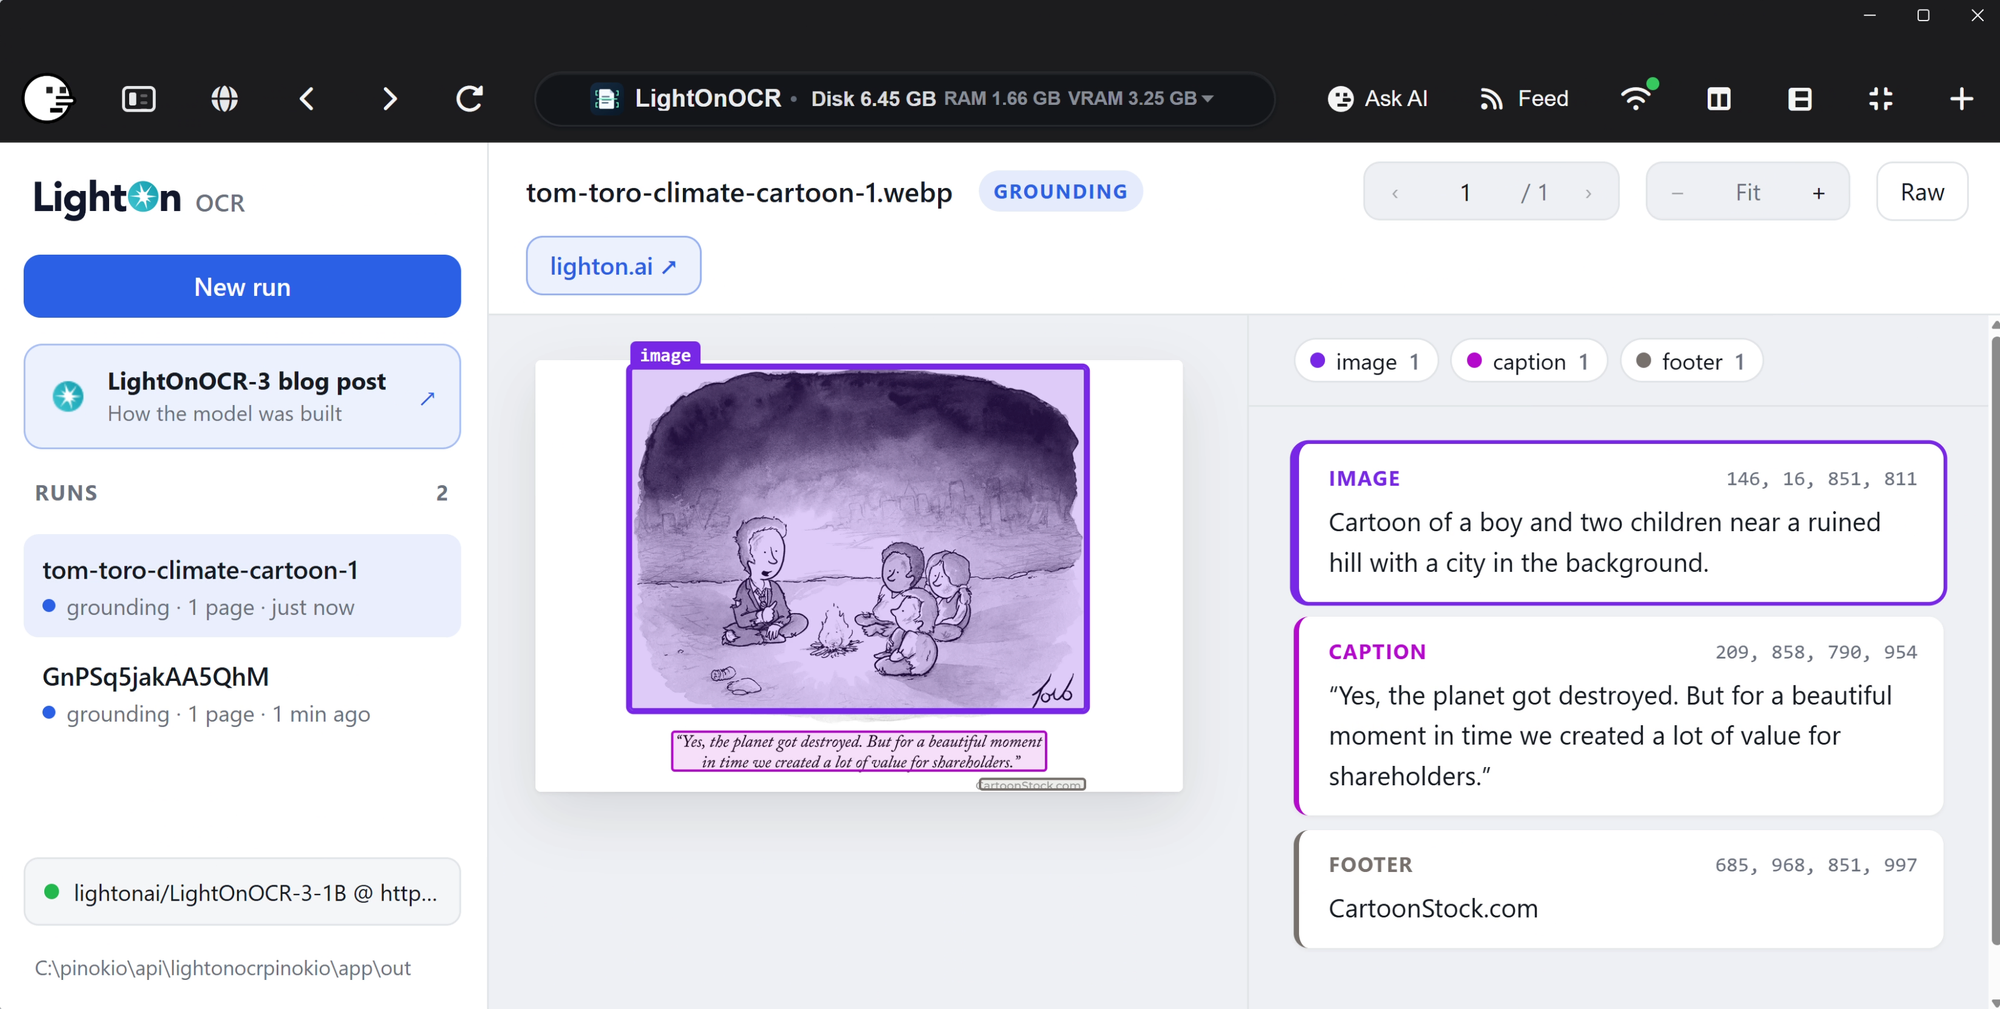
LightOnOCR-3: Turn PDFs and images into structured text locally (Mac, Windows, Linux)LightOnOCR 3 is now available on Pinokio. It's a sequel to the LightOnOcr 2 model, which you can try here (thanks to @theawakenone ) https://pinokio.co/apps/github-com-theawaken1-lightonocr-2-1b-pinokio This LightOnOCR 3 launcher implements the backend using huggingface transformers and lets you run 3 variations of the model: - 0.8B - 1B - 4B The launcher includes LightOn’s original web interface, available at: https://github.com/lightonai/LightOnOCR Demo Here's how it works. You just launch the app and open any PDF or image file: Features - View the source document alongside the extracted text - inspect layout boxes showing where content came from - revisit previous runs. Examples
Type:api
apipluginAll
Platform:All
AllmacOSWindowsLinux
GPU:All
AllNVIDIAAMDApple
Sort by
RecommendedLatestCheck-ins
#ai191#tts60#image-generation46#video-generation40#137#utility35#music33#próba27
Stable Audio 3Featured
Launcher for Stable Audio 3 Small Music, Small SFX, and NVIDIA Medium using public cocktailpeanut Hugging Face mirrors. https://github.com/Stability-AI/stable-audio-3
cocktailpeanut/stable-audio-3-small.pinokiov7.0updated 1mo ago
#ai#music#music-generation
@cocktailpeanut14 check-insNVIDIAAMDApple
DramaBoxFeatured
Expressive TTS with voice cloning, prompt-driven speech synthesis built on LTX-2.3 by Resemble AI
PierrunoYT/DramaBox-TTS-Pinokiov5.0updated 15d ago
#tts#ai#voice-clone
@pierrunoyt8 check-insNVIDIAAMDApple
HiDream O1 Image FP8Featured
One-click launcher for the original HiDream-O1-Image web UI using lazy-downloaded drbaph Dev or Full FP8 checkpoints through a root FP8 runner. Requires an NVIDIA CUDA GPU.
cocktailpeanut/hidream-o1v7.0updated 2mo ago
#ai#image-generation
@cocktailpeanut3 check-insNVIDIAAMDApple
ds4-webuiFeatured
Pinokio launcher and standalone Web UI for ds4.c, a Metal-only DeepSeek V4 Flash inference server.
cocktailpeanut/ds4.pinokiov7.0updated 3mo ago
#ai#llm
@cocktailpeanut0 check-insNVIDIAAMDApple
VoxCPMFeatured
Tokenizer-free multilingual TTS and voice cloning with low-VRAM and VoxCPM2 Web UI/API launch modes.
IAnMove/voxcpm2-pinokio-launcherv7.0updated 14d ago
#tts#ai
@theinaog2 check-insNVIDIAAMDApple
PhospheneFeatured
Local generative video, image, and character training on Apple Silicon. Train face + voice LoRAs in-app. Q8 HQ for character clips. MLX native — no cloud, no API key.
mrbizarro/phosphenev7.0updated 4h ago
#video-generation#phosphene#ai
@bizarro39 check-insNVIDIAAMDApple
OverworldFeatured
[NVIDIA GPU REQUIRED] Realtime world generator by Overworld Waypoint world model
cocktailpeanut/overworld.pinokiov7.0updated 3mo ago
#ai#realtime#world-generation
@cocktailpeanut7 check-insNVIDIAAMDApple
TexturizerFeatured
Minimal NVIDIA-first web app for texturing existing meshes with Hunyuan3D-2GP/mmgp while preserving rigged GLB structure when the vertex layout stays compatible.
cocktailpeanut/texturizerv7.0updated 5mo ago
#3d#3dgen#ai
@cocktailpeanut4 check-insNVIDIAAMDApple
AI4AnimationPyFeatured
A Python framework for AI-driven character animation using neural networks.
cocktailpeanut/ai4animationpy.pinokiov7.0updated 2mo ago
#3d#ai
@cocktailpeanut5 check-insNVIDIAAMDApple
StripperFeatured
Strip image metadata locally in the browser.
cocktailpeanut/stripperupdated 5mo ago
#image-edit#utility
@cocktailpeanut2 check-insNVIDIAAMDApple
EuphonyFeatured
Automatically discover local Codex sessions and browse them with Euphony.
cocktailpeanut/euphony.pinokiov7.0updated 5mo ago
#ai#chatgpt#openai
@cocktailpeanut8 check-insNVIDIAAMDApple
WorldMirror 2.0Featured
[NVIDIA] Pinokio launcher for the released WorldMirror 2.0 reconstruction app from HY-World 2.0. Uses a cu128 PyTorch baseline with gsplat from PyPI/JIT. https://github.com/Tencent-Hunyuan/HY-World-2.0
cocktailpeanut/worldmirror.pinokiov7.0updated 5mo ago
#3d#ai#gaussian
@cocktailpeanut6 check-insNVIDIAAMDApple
LingBot-MapFeatured
NVIDIA launcher for LingBot-Map, a streaming 3D reconstruction viewer from Robbyant.
cocktailpeanut/lingbot-map.pinokiov7.0updated 5mo ago
#3d#ai#gaussian-splat
@cocktailpeanut2 check-insNVIDIAAMDApple
AceJAMFeatured
Describe any song in plain English, compose it locally with an embedded Qwen GGUF model, and generate it with ACE-Step v1.5.
cocktailpeanut/acejam.pinokiov7.0updated 4mo ago
#ai#song
@cocktailpeanut13 check-insNVIDIAAMDApple
ReClipFeatured
Self-hosted, open-source video and audio downloader with a clean web UI. Supports YouTube, TikTok, Instagram, X, and 1000+ other sites via yt-dlp.
krynsky/reclip-pinokiov5.0updated 29d ago
#utility
@krynsky8 check-insNVIDIAAMDApple
AniGenFeatured
[NVIDIA GPU required] Unified S^3 fields for animatable 3D asset generation from a single image. 6GB VRAM needed (Low VRAM option)
cocktailpeanut/anigen.pinokiov7.0updated 5mo ago
#3d#ai
@cocktailpeanut4 check-insNVIDIAAMDApple
OVIEFeatured
Generate novel views from a single image with an auto-downloading OVIE web UI.
cocktailpeanut/ovie-webuiv7.0updated 6mo ago
#ai
@cocktailpeanut5 check-insNVIDIAAMDApple
Axios InspectorFeatured
Run a minimal IOC sweep for the March 30-31, 2026 axios npm compromise.
cocktailpeanut/axios-inspectorv5.0updated 6mo ago
#security
@cocktailpeanut4 check-insNVIDIAAMDApple
Hermes ModFeatured
A full Hermes skin manager for browsing, editing, saving, and activating CLI skins directly from Pinokio.
cocktailpeanut/hermes-modv6.0updated 3mo ago
#hermes#agent#utility
@cocktailpeanut11 check-insNVIDIAAMDApple
Side-StepFeatured
Optimized Training script for Ace-Step with low VRAM support for local GPUs.
6Morpheus6/Side-Stepv5.0updated 5mo ago
#lora-training#song#training
@morpheus4 check-insNVIDIAAMDApple
Previous
12345...9
NextPage 2 of 9

Global feed

Latest posts from the community.

Just wanted to thank you guys for keeping this going MrBoozeNut, DeepMorpheus & Blizzy Bliz. I've bee...
@midipunk · Maestro
I've downloaded the github GEV zip and extracted it to a folder. I've installed Pinokio and clicked t...
@snacko · God's Eye View1
Travail parfait , je suis loin de celà notamment pour la musique et le titrage, je travaille encore m...
@arkinou · MiniMax H3 Studio1
New on Pinokio
@cocktailpeanut · theprototype.app
Automatically discovered via GitHub
Why i am unable to access all map resources? ESRI and OSM only working. I don't have any API's.... Ca...
@idrispaatwala6 · God's Eye View1
More

Global radar

Projects getting attention.

Followed·2 min
Comfyui
The most powerful and modular diffusion model GUI, api and backend with a graph/nodes interface. https://github.com/comfyanonymous/ComfyUI
Followed·5 min
Wan2GP
1-click WanGP Launcher. Super Optimized Gradio UI for AI video creation for GPU poor machines (6GB+ VRAM). Supports Wan 2.1/2.2, Qwen, Hunyuan Video, LTX Video and Flux. https://github.com/deepbeepmeep/Wan2GP
Followed·6 min
Image to Prompt
Generate editable Ideogram JSON prompts from uploaded images.
Followed·12 min
Maestro
An all-in-one, 100% local AI creative studio, director, and multi-track editor. Generate with MiniMax H3, LTX-2.5/2.3, Wan, Flux, Qwen, and more; turn an idea or song into a planned production; then finish it on the timeline. Requires an NVIDIA GPU (6GB+ VRAM).
Followed·12 min
audiocraft_plus
AudioCraft Plus is an all-in-one WebUI for the original AudioCraft, adding many quality features on top https://github.com/GrandaddyShmax/audiocraft_plus
More
Pinokio
PrivacyTerms
FeedApps